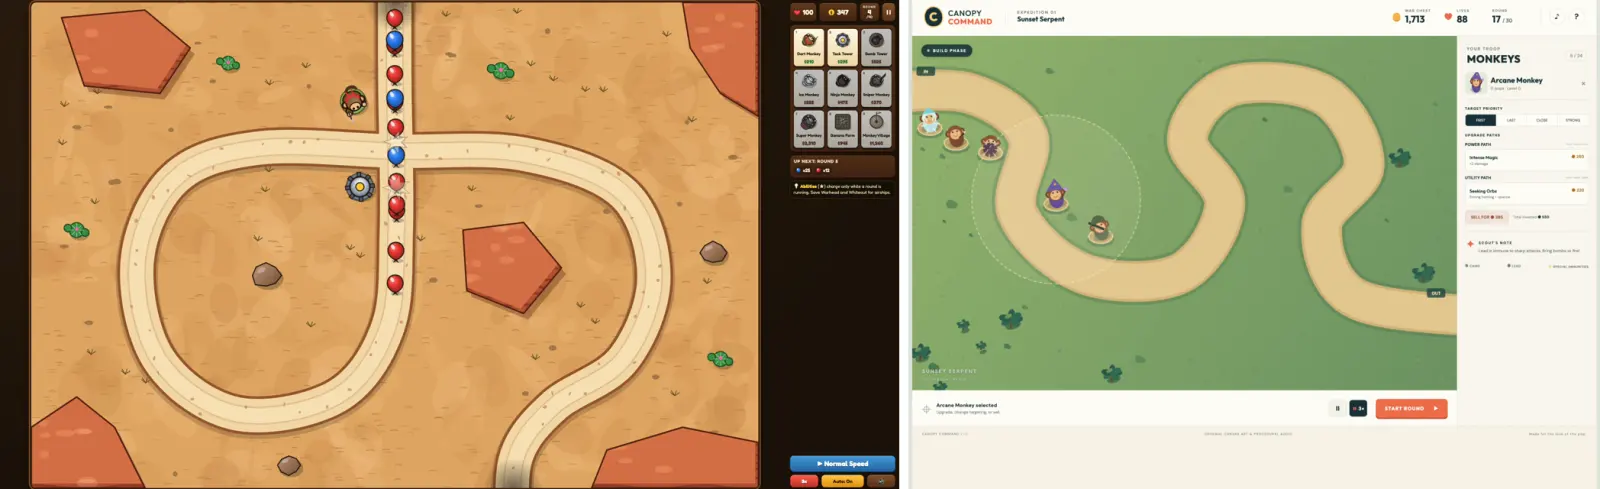
One of these games cost about $40 to build. The other cost $1.73. Same prompt, same tool. The $40 game on the left is from Claude Opus 5.5, and the $1.73 game on the right is from Kimi K3.1 Pro.
Moonshot AI is a Chinese company that builds high-quality open-weight models. It launched K3.1 Pro on October 23 and pitches it as an Opus-level model at half the price. Its launch charts put it first on 6 of 14 benchmarks and in the top two on 11. So I gave it three tests the other models have already done.
How I ran it
Same prompts, word for word, each in an empty folder with nobody answering questions. Kimi ran in Claude Code through OpenRouter. I set it to extra-high effort on the first two tests and high on the third to match the other models, though OpenRouter may have ignored that setting.
Each model got one run per test, so don't read too much into small gaps. Costs for the other models are at list API prices, even where a subscription covered the run.
Test 1: Bloons TD
The prompt asks for a full Bloons-style tower defense game: towers with upgrade paths, different balloon types, rounds that get harder and a big MOAB boss at the end. It also tells the model to keep going until the game is finished and tested.
| Model (extra-high) | Score | Time | Cost |
|---|---|---|---|
| Claude Opus 5.5 | 8.3 | 1h 37m | $39.96 |
| Claude Sonnet 5.5 | 7.8 | 2h 15m | $40.03 |
| Claude Fable 5.1 | 7.5 | 54 min | $27.26 |
| GPT-6.1 | 5.8 | 33 min | $1.88 |
| GPT-6 Astra | 5.6 | 27 min | $7.71 |
| Claude Haiku 5.5 | 5.3 | 33 min | $3.25 |
| GPT-6 Sol | 5.0 | 20 min | $2.29 |
| Kimi K3.1 Pro | 4.9 | about 24 min | about $1.73 |
| GPT-6 Luna | 4.6 | 17 min | $0.08 |
Opus's game has 3 maps, 9 towers, 72 upgrades, and a save so you can come back later. Kimi's has 1 map, 6 towers and 36 upgrades.
Kimi's game also has real bugs. Pops make no sound and no burst. Ice never stops slowing a balloon, so they pile up in a frozen jam at the entrance. The title screen promises 30 handcrafted rounds, but rounds 21 to 29 come from a formula, and I lost 43 lives on round 21 alone.
It's cheap, I'll give it that. But it performed like a cheap model, and the only model here it beat was GPT-6 Luna, by not much.
Every score comes from one written rubric, which the Lab's Bloons page explains. Play them yourself: Opus's game, Kimi's game, or all 41 builds.
Test 2: Squishy gummy bears
This one asks for see-through gummy bears on a table, in a single HTML file, that you can grab, stretch, squash, throw and pour.
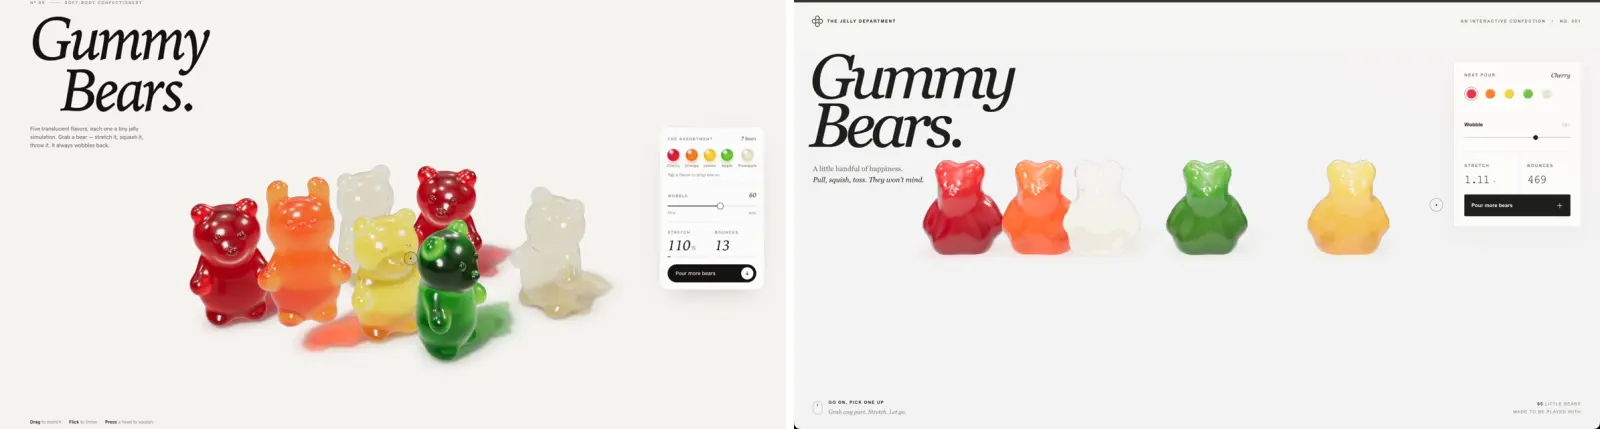
Opus is on the left and Kimi is on the right. Kimi's isn't terrible, but the bears don't really have feet, and dragging them around doesn't feel great. Opus's look far better and the physics are much more convincing.
| Model | Score | Time | Cost |
|---|---|---|---|
| Claude Opus 5.5 | 9.7 | 49 min | $13.48 |
| GPT-6 Astra | 9 | 17 min | about $4.69 |
| Claude Fable 5.1 | 8.5 | 89 min | $40.07 |
| Gemini 4 Argon | 8 | 51 min | about $3.97 |
| GPT-6.1 Sol | 6.5 | 31 min | about $1.68 |
| Kimi K3.1 Pro | 5 | 34 min | about $1.37 |
| Grok 4.7 | 3.5 | about 69 min, then it hung | none |
| Gemini 3.1 Pro | 1 | 3 min | about $0.45 |
That's sixth of eight, ahead of only Grok and Google's older Gemini model. Again, it was cheap, and again it performed that way.
Play them yourself: Opus's bears, Kimi's bears, or every build.
Test 3: A landing page
The first two tests are a little out of the ordinary. This one is more everyday: a waitlist page for a made-up HR startup called Fernway, from a short brief. And this is where Kimi finally did well.
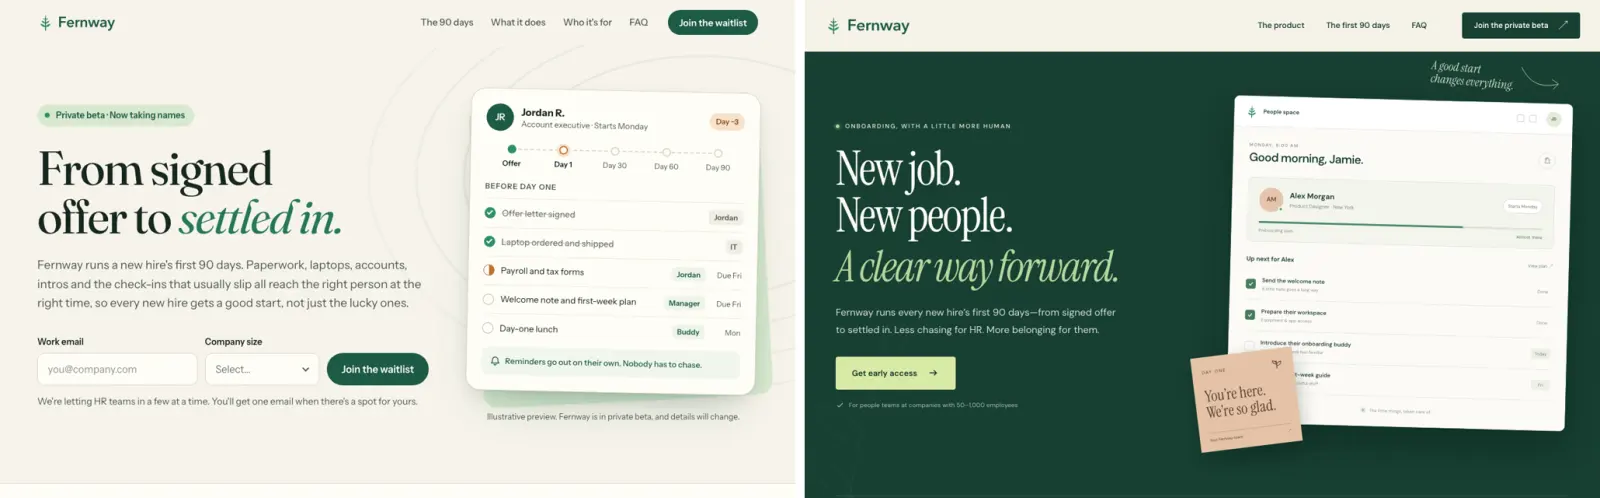
Opus is on the left and Kimi is on the right. Kimi's looks good: the graphics, the colors, the accordions you can open. The one thing I wish it had was more animation. Opus's is similar overall with better animation, so I put it just ahead, but it's close and fairly subjective. I could see someone preferring Kimi's.
| Model | Score | Time | Cost |
|---|---|---|---|
| Claude Opus 5.5 | 8.5 | 8 min | $2.17 |
| Kimi K3.1 Pro | 8 | 12 min | about $0.86 |
| GPT-6.1 Sol | 7.5 | 12 min | about $0.40 |
| GPT-6 Astra | 7.5 | 10 min | about $2.14 |
| Claude Sonnet 5.5 | 7 | 4 min | $0.57 |
To be fair, all five did well, and I was nitpicking to separate them.
See them yourself: Opus's page, Kimi's page, or all ten pages.
The price
Kimi K3.1 Pro costs $2 per million input tokens and $10 per million output tokens. That's half of Opus 5.5 and the same as Sonnet 5.5. It also wrote less code than Opus on the big builds, so the three runs came to about $3.96, against about $55.61 for Opus.
So is it Opus for half the price?
No. In my testing, the claim that it's an Opus-level model doesn't hold up. At best it's Sonnet-level.
For straightforward work like a generic landing page, it's good value. For complex or unusual work, the kind you'd give Opus or Astra, I'd pay the extra money for the better model.
Every build and prompt is on the Lab pages linked above, so you can try them and judge for yourself.